For a long time, the primary goal of a Data Scientist was to find the best algorithmic recipe to solve a given business problem. To facilitate this prototyping phase, many tools have emerged, such as open-source libraries and Data Science platforms; the latter even offering no-code experiences.
·
Apr 14, 2022
However, an essential aspect of an artificial intelligence project has been ignored for too long: industrialization. We must not lose sight of the fact that only an AI in production—that is, a system whose results (forecasts, recommendations, etc.) are made available to end users—can deliver significant productivity gains for companies.
According to Gartner, nearly 85% of AI projects fail to reach production. And for those that do, the conclusion is clear: costs are high and constraints are numerous. So, what explains this "industrialization wall"?
Deploying and redeploying the Machine Learning model
Once the algorithmic recipe is validated during prototyping, it becomes necessary to confront the model with dynamic data arriving in real time. The production environment must have a stable and high-performance data connector (databases, web APIs, cloud storage spaces, etc.).
The prototyping results are then put to the test against real-time data, which is too often different from the prototyping data. The method must therefore be revised.
After this first hurdle, the code must become more maintainable and performant to move into production, handling the load and supporting every update. This code refactoring (refactoring) is a necessary step; optimizing too early would be counterproductive, reducing the agility of prototyping. The production environment must be suited to this conversion of methods between prototyping and production.
"Scaling and integrating into production information systems require specificskills that multiply the initial cost of the project."
Scaling and integrating into production information systems require specific and highly sought-after—meaning expensive—skills, such as ML Engineers / DevOps / Developers, which multiplies the initial cost of the project. A manual, non-capitalized approach to these steps makes production possible in theory, but expensive, time-consuming, and perilous from one deployment to the next.
The difficulties become even more significant when it comes to modifying and updating the algorithmic recipe, which is rarely static once in production. Each redeployment is very time-consuming, as it requires repeating the production steps. Consequently, updates become very cumbersome to redeploy, which may encourage keeping unsuitable solutions in production or spending an enormous amount of time on redeployments.
Friction during production deployments often leads to the abandonment of solutions: they are too cumbersome, too risky, and too time-consuming.
Monitoring production
Once the model is deployed, constant supervision is necessary to allow teams Data to be alerted to service malfunctions, if possible in advance; to diagnose them and to correct them.
Two different types of malfunctions can occur.
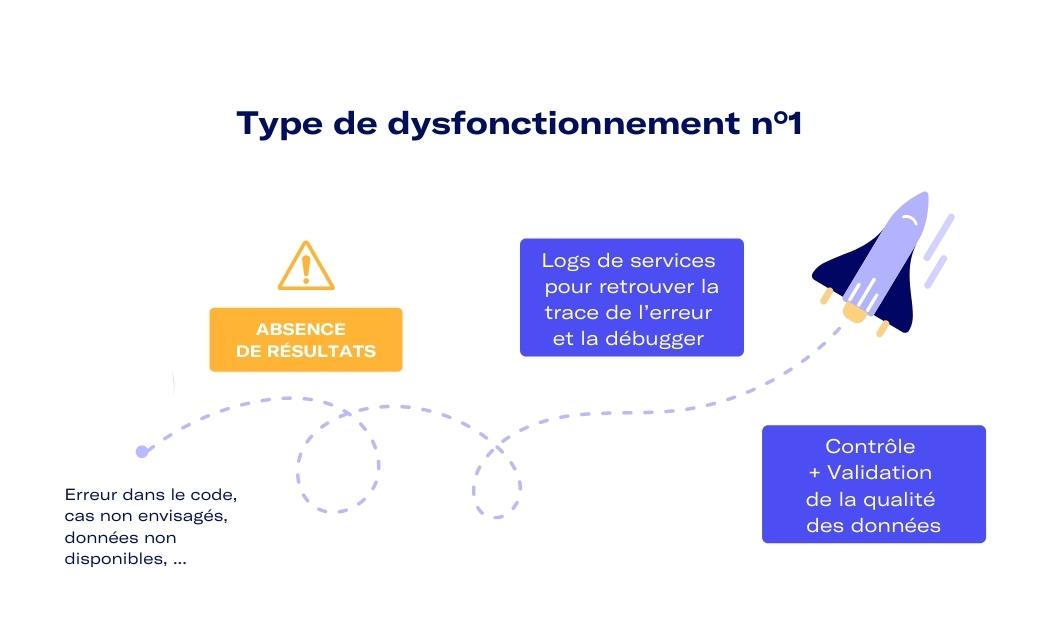
The first possible malfunction: users no longer receive results. This can stem from a code error, an unforeseen edge case, or the unavailability of source data...
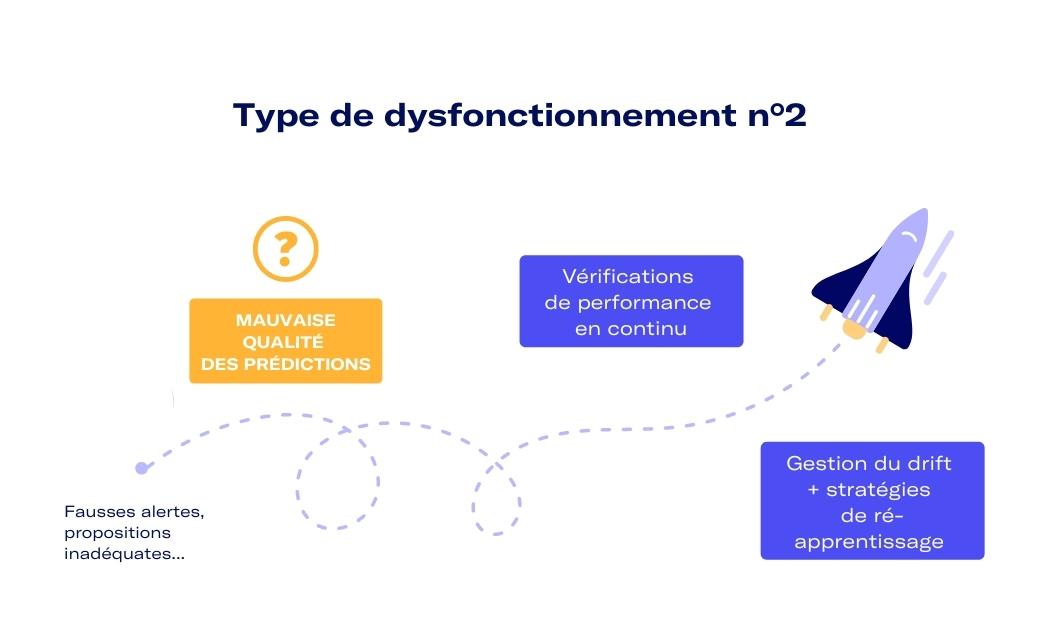
The second possible malfunction, more specific to Machine Learning services: users receive predictions, but they are of poor quality. This happens, for example, when a predictive maintenance service triggers too many false alarms or a recommendation engine sends irrelevant or uninteresting suggestions. In this situation, the system is operational from a software perspective, but not from a business perspective, which can lead to lower AI adoption due to a loss of trust in its results.
For the first type of malfunction, having service logs to be able to trace the error and debug it will be key. Operational observability is crucial here. It drastically reduces the time required to identify and fix the service.
Furthermore, to prevent service interruptions related to input data, Data Scientists or ML Engineers must implement data quality checks and validations (for example, verifying data types, data loss, missing data, outliers, changes in data field names, etc.).
"Operational observability is crucial here. It drastically reduces the time required to identify and fix the service."
For the second type of malfunction, it proves much less obvious to detect. Identifying a loss in the mathematical performance of a Machine Learning model requires more complex management strategies. A primary challenge is to implement continuous performance checks and trigger alerts when performance declines. This involves managing drift (drift), retraining strategies, and in some cases, modifying the models.
To support deployment and maintenance, Data teams will need, among other things, version management tools (versioning) and experiment tracking (tracking): to be able to revert to any previous state (with the correct version of the data, code, model, etc.) simply and securely, and to compare models against one another.
The road to production is long and winding for services to Machine Learning deliver long-term value.
Optimizing algorithmic recipes, managing production environments, refactoring code, updating models, handling drift, retraining, and more. These are all key stages and potential friction points that can jeopardize the industrialization of an AI project.
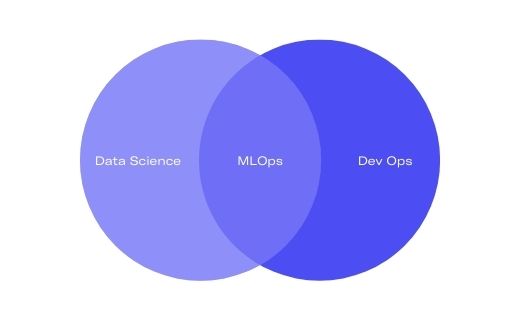
All of these functions sit at the intersection of Data Science and DevOps expertise.
This is why the emergence and adoption of MLOps (Machine Learning Operations) is so important: it finally provides teams with Data a methodology and tools to confidently clear the hurdle of industrialization.
By also reducing production costs and increasing the reliability of results, MLOps has everything it takes to help artificial intelligence reach its true potential.
Subscribe to our Newsletter
Stay up to date with the latest news, articles, and updates. Subscribe now!
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.